Introducing PingBoard
Uptime monitoring is a solved problem that's somehow still expensive. The hosted tools charge per monitor, per status page, per seat — the meter runs on things that cost them nearly nothing. The serious self-hosted options ask you to run a small datacenter: an app server, a database, a cache, a queue, four containers before you've checked a single URL. And the lightweight classics work, but their interfaces haven't moved in a decade.
We wanted the boring middle: a monitor you'd actually enjoy opening, running as one container on the box you already have. That's PingBoard, and it's open source (MIT) as of today.
What it is
docker run -d --restart=always \
  -p 3000:3000 \
  -v pingboard:/data \
  --name pingboard \
  ghcr.io/steiner-co/pingboard:latest
One container, one volume, one port. Inside there's a Bun server, an embedded SQLite database, and an in-process scheduler — no Redis, no queue, no external database to babysit. Open http://localhost:3000, create the admin account, add your first monitor. Under a minute, honestly.
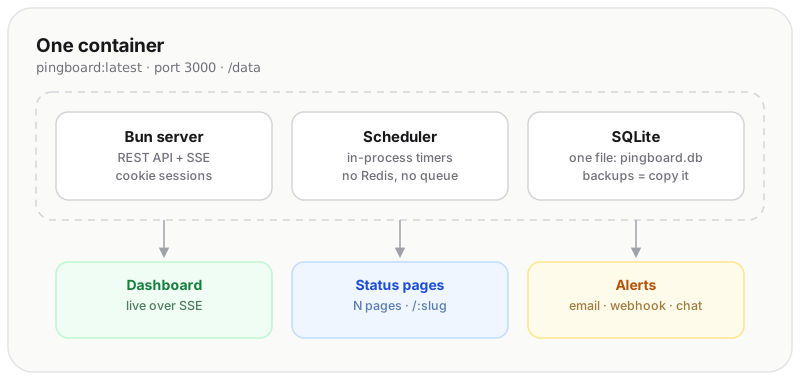
Everything the dashboard does is a REST call, and the public status pages are served by the same process, from the same database. That sounds unremarkable until you've debugged a status page that disagrees with your monitoring because a cache, a replica, or a deploy got in between. Here there is nothing in between: the page your customers see reads the same heartbeats you see. If the dashboard says the API is down, the status page says the API is down, because there is exactly one place that fact can live.
The dashboard updates live over Server-Sent Events instead of polling. A status change appears within a couple of seconds, with no refresh button and no spinner. SSE is a deliberately unfashionable choice — one-way push over plain HTTP, debuggable with curl, reconnects for free — and it turns out to be everything a monitoring dashboard needs.
The feature tour
PingBoard covers the checks indie hackers actually run and skips the rest. No synthetic browser flows, no marketplace of forty integrations, no knobs you'll never touch. Here's what's in the box.
Monitor types
Six monitor types, each with its own sensible defaults:
| Type | What it checks |
|---|---|
| HTTP(S) | Status codes plus optional keyword or JSON-path assertions on the body |
| TCP | Can a connection be opened to host:port |
| Ping | Classic ICMP round-trip |
| DNS | Resolves a record and optionally matches its value |
| SSL expiry | Certificate lifetime with warning/critical thresholds |
| Push | Heartbeat monitors for cron jobs and backups, with a grace period |
Domain expiry launched as a seventh type here; as of 1.0 it's a tracker of its own — expiry, registrar, nameservers, and SSL across your whole portfolio, on its own page, API, and MCP surface.
The HTTP assertions deserve a callout: a 200 that says "database":"down" is not up. Keyword matching catches the maintenance page served with a smile and a 200 status; JSON-path assertions catch the API that's technically responding and functionally broken. These are the checks that page you at 3am for a reason, instead of paging you because a CDN hiccuped once — retries are configurable per monitor, so a single missed check doesn't become an incident.
Push monitors work the other way around. Your backup script or nightly job pings PingBoard on success; if the ping doesn't arrive within the interval plus a grace period, that's the incident. Silent cron failures are the ones that hurt most — you discover them when you need the backup — so the grace period exists to absorb normal jitter without masking real silence.
Status pages
As many status pages as you want, each with its own slug, optional password protection, and curated monitor groups ("API", "Web", "Database"). Every monitor gets a 90-day uptime strip, average response time, and its recent incident history — the standard vocabulary your customers already know how to read:
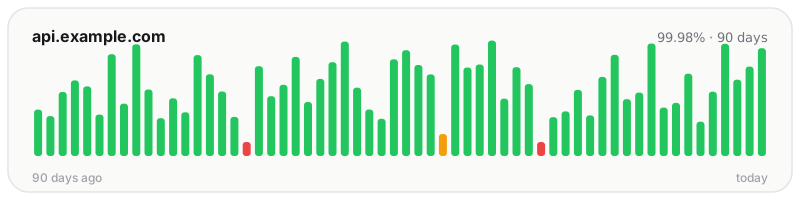
Pages ship in light and dark (the visitor picks, or follows their system), with twelve theme presets plus a visual custom-theme builder, custom CSS per page, your own logo and website link, and a white-label toggle that hides the "Powered by PingBoard" footer. Free, on every page — things other tools charge per page for. Live updates come over SSE there too, so a customer staring at the page during an outage watches it recover in real time.
Notifications
Five channels, each suited to a different kind of urgency:
- Email — delivered through your own SMTP, so there's no third party standing between an outage and your inbox.
- Webhook — a generic POST with a documented JSON payload. Anything programmable on your end is covered.
- Discord and Slack — drop alerts where the team already argues about deploys.
- ntfy — self-hosted push notifications, popular with exactly the crowd that self-hosts monitoring.
Channels link to monitors individually, so the database alerts can page the on-call topic while the marketing site just posts to a channel. Every channel has a "send test" button, because an alerting path you've never fired is a rumor, not a system.
Alerts fire when an incident opens and again when it recovers, with the downtime duration included. Recovery messages matter more than people think — they're what lets you close the laptop instead of wondering.
Maintenance windows
Schedule planned downtime per monitor. Checks keep running and history stays honest, but incidents — and therefore notifications — stay quiet, and the status page shows the window as the reason.
| Pause | Maintenance window | |
|---|---|---|
| Checks keep running | No | Yes |
| History shows | A gap | The planned window |
| Notifications | Silent (nothing runs) | Suppressed, explained |
| Status page | Monitor disappears | Shows the reason |
Strictly better than the pause button for deploys: pausing rewrites history into a gap, while a maintenance window tells the truth about it.
API tokens
Tokens carry the same access as the admin account, travel as Bearer auth, are shown once at creation, and revoke instantly. Provision monitors from a deploy script, silence alerts from a runbook, pull uptime stats into your own reporting:
curl -H "Authorization: Bearer pb_..." \
  http://localhost:3000/api/admin/monitors
Everything the dashboard does is available, because the dashboard is just another API client.
An MCP server
Point Claude Code, Cursor, or Zed at your instance and ask things you'd never click through a UI to find out:
"Which monitors are down?"
"Why did the API check fail this morning?"
"Schedule maintenance on the database for tonight 2–4am."
Twenty-two tools, read-only ones annotated as such, deletes marked destructive. Monitoring data is exactly the kind of thing that's painful to browse and trivial to ask about, so meeting the assistant where it lives felt obvious.
Principles
Two rules shaped the build, and both are about what we refused to do.
Self-hosted means unlimited
No monitor caps, no page caps, no seat counts, no feature flags waiting on a plan. Your instance, your hardware, your call. The hosted tools' per-monitor pricing is possible because their marginal cost per check is low and their customers can't verify it — self-hosting collapses that entire conversation. If your $5 VPS can run the checks, you can have all of the checks.
This also shaped the data model: every ID is a UUID, monitor and channel configs live in JSON columns so new types don't need migrations, and heartbeats roll up into daily aggregates after the retention window. The database file stays small enough to copy, which is the whole backup strategy: stop the container, copy one file, restart.
Simple is a feature
One binary-feeling container means upgrades are "pull and recreate" and failure modes fit in your head. We picked boring technology — SQLite, SSE, setTimeout — on purpose, and said no to everything that would need orchestrating: no Redis, no queue worker, no separate scheduler container, no YAML configuration with a second source of truth. The UI is the only configuration interface; env vars exist only for boot-time concerns like the port and the data directory.
Boring has a failure mode of its own, which is staleness — the dated interfaces that sent us here in the first place. So the simplicity budget all went into the interface: a modern component set, real-time everything, status pages you'd show a customer without apologizing. Simple underneath, polished on top.
Try it
The quickstart, monitor-type reference, and self-hosting guide are in the docs. Source, issues, and the release workflow live on GitHub — MIT licensed, contributions welcome.
If you've been paying a per-monitor invoice for a cron job with a dashboard, this one's for you. And if you point a status page at your own projects this week, we'd genuinely like to hear how it goes — the discussions tab is open.